Last night our render pipeline encountered a strange symptom: ComfyUI still responded to HTTP normally, the job queue kept moving, but the GPU did absolutely zero work — not even one percent. The entire render batch just sat there, with no clean error message to look at. This note tells the story of the "wedge" condition and the auto-recovery ladder we built into the pipeline.
The wedge symptom encountered
Three signals appeared simultaneously:
- The server process was alive, responding to HTTP requests on every endpoint
- The job queue "appeared" to be moving, but no renders were flowing out
- GPU utilization (gpu_util) was stuck at zero for over 60 seconds, despite jobs waiting in the queue
This kind of symptom is more dangerous than a complete crash, because monitoring systems that only check "is it responding?" will see everything as normal, even though production has ground to a halt.
Detection method: Don't trust HTTP alone
The key lesson is that health checks must measure "is work flowing?" not just "is the server responding?" We therefore added monitoring of gpu_util — if the queue has jobs but gpu_util stays at zero for over 60 seconds, the system declares a wedge and immediately begins recovery steps.
The COMFY_HEAL ladder
When a wedge is detected, the system climbs the recovery ladder step by step, with a 180-second time ceiling per cycle — never allowing an endless restart loop:
| Step | Action | Condition |
|---|---|---|
| 1 | Restart only the wedged process (identified by PID, not name) | Wedge detected on primary GPU |
| 2 | Fail over to backup GPU on same machine | Still not working after restart |
| 3 | Safely abort entire batch, alert team | First two steps failed |
The most critical point is the restart — we must terminate only our own process, identified by PID. Never kill by program name, because multiple services with similar names run on the same machine.
Test results
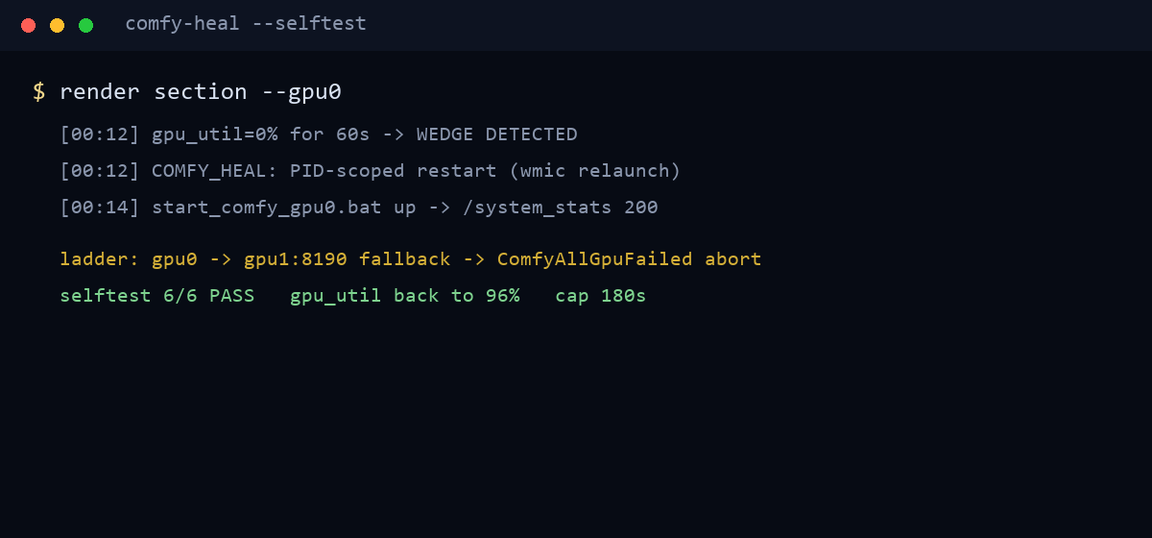
- Offline selftest passed all 6/6 cases (detection, restart, re-check, failover, time ceiling, safe abort)
- The restart mechanism was proven in a real incident during clip production — the stuck job was re-rendered and aired as scheduled
- After recovery, gpu_util returned to 96% within two minutes
Next steps
The next step is to roll out this "measure work flow" health check to all other services in the fleet, including tracking weekly wedge statistics to see if this symptom correlates with any particular job type — stay tuned for the next Lab Notes issue.
